Overview
Vannevar is a local RAG search tool for Markdown. It builds a hybrid index over a directory of notes with field-aware BM25 keyword search via SQLite FTS5 and semantic vector search via HNSW, then fuses the ranked lists with weighted Reciprocal Rank Fusion.
Everything runs offline. The default EmbeddingGemma profile runs through portable ONNX, while new Apple Silicon indexes can use llama.cpp and Metal when the optional runtime is installed. Selected models download once into a local cache; indexing and search stay on the local machine.
It is named after Vannevar Bush, who envisioned the Memex, a device for storing, linking, and retrieving personal knowledge.
Features
Hybrid search
FTS5 ranks chunks by BM25 keyword relevance. The vector store embeds the query with the same model used at index time and finds nearest neighbors via HNSW cosine similarity. RRF merges the two ranked lists with score = weight / (k + rank) at k=60, deduplicating chunks that appear in both, and normalizes so the top result is 1.0.
The CLI also exposes the underlying searches directly: search for BM25 only and vsearch for vector only, so you can fall back to whichever side fits the query.
Markdown-aware chunking
The chunker respects heading hierarchy, keeps fenced code blocks and tables atomic, and applies configurable overlap between chunks so an answer that straddles a chunk boundary still surfaces.
Fully local
No API keys, no cloud calls. The embedding model is ~111MB and downloads on first use; after that, everything (embedding, indexing, search) runs on the local machine.
Root-aware indexes
Directory indexes store each document as root path + relative path, so a single database can hold multiple indexed directories with overlapping filenames. get accepts a unique relative path, an absolute path, or a # document/chunk ID prefix.
Fast
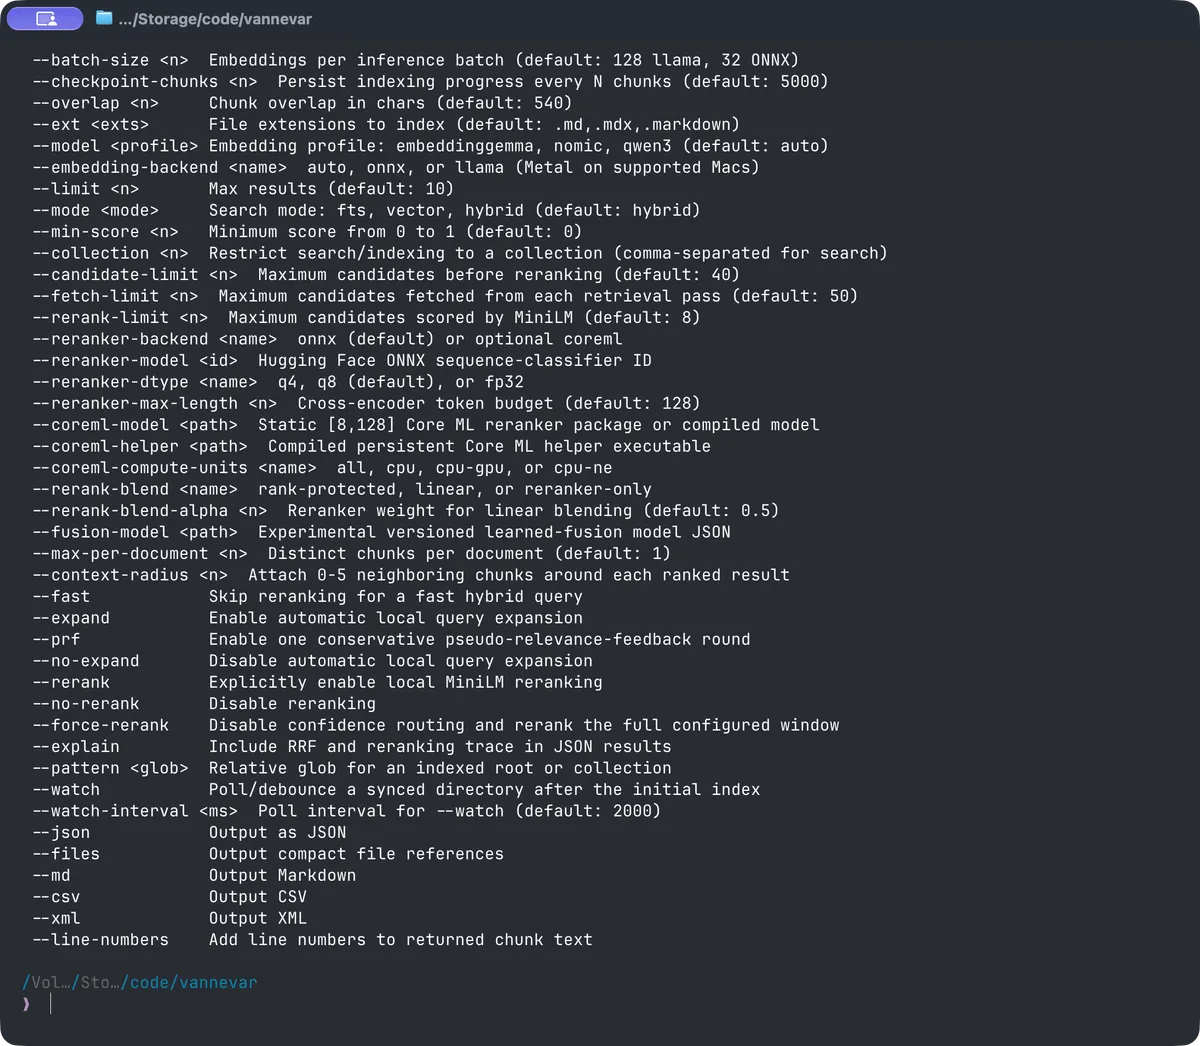
Performance depends on corpus, embedding backend, and retrieval options. Use --fast or --no-rerank to skip local reranking when latency matters; the repository includes workload-specific benchmarks and relevance fixtures.
Quick start
# Index a directory of markdown files
bun src/cli.ts index ./docs

# Hybrid search (default)
bun src/cli.ts query "how to configure authentication"

# Keyword search only (BM25)
bun src/cli.ts search "authentication config"

# Vector search only
bun src/cli.ts vsearch "setting up user login"

# Retrieve a chunk or document
bun src/cli.ts get setup.md
bun src/cli.ts get '#<chunk-or-document-id-prefix>'
Output flags cover --json, --md, --csv, --xml, and --files for compact file references.
Architecture
Indexing runs in two phases with pipelining: read and chunk first, then embed and store. The store is SQLite via bun:sqlite and Drizzle ORM, with an FTS5 virtual table for keyword search. The vector side wraps verso-db for the HNSW index, so the same vector store I use elsewhere drives the semantic half of the search.
Technology stack
- TypeScript on the Bun runtime, using
bun:sqlite,Bun.file, andBun.CryptoHasher - SQLite with Drizzle ORM for storage, FTS5 with porter stemming for keyword search
- verso-db HNSW index for vector search
- EmbeddingGemma embeddings via @huggingface/transformers (portable ONNX), with optional native llama.cpp/Metal embeddings on Apple Silicon
- Biome for linting